Memo: The Unit Was Never the Token
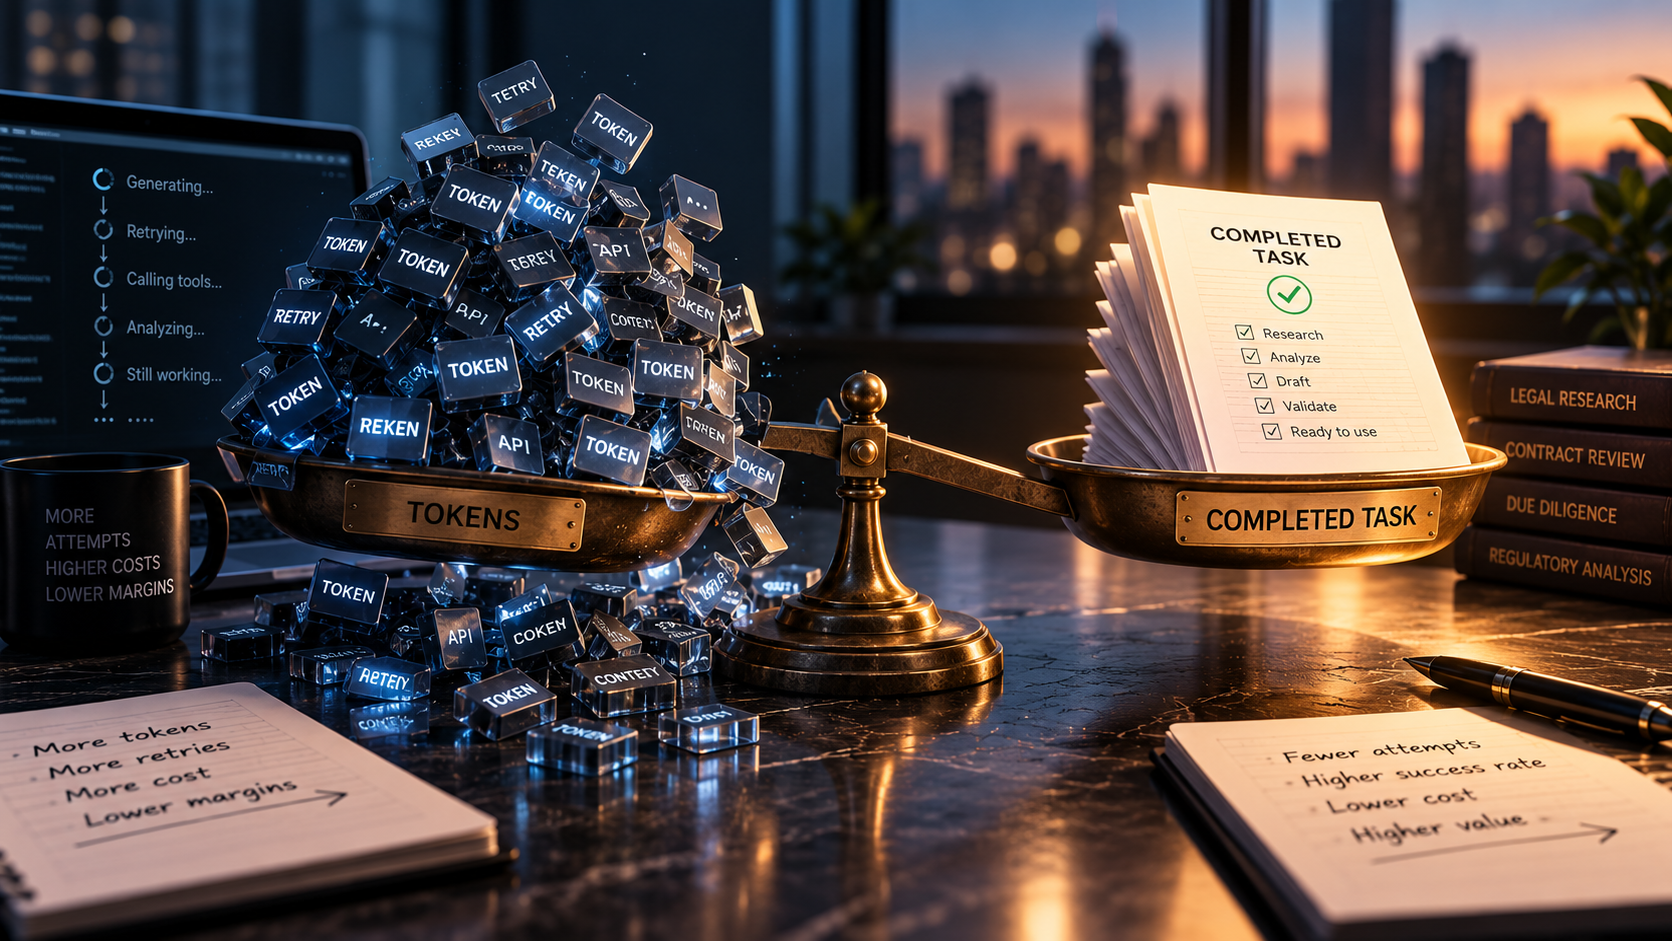
Harvey's gross margin went from about +50% to about −50% in six months, then back to positive. Every retelling reads it as a story about expensive frontier models and cheap open weights. The numbers don't support that. Open-weight serving was only about 40% cheaper per token, which cannot produce the 90% cost reductions Harvey reports – and within a day of the news, both frontier labs cut prices below the open-weight option Harvey had moved to. What actually broke was the shape of the contract: fixed per-seat revenue against metered cost. What actually fixed it was a higher task success rate, not a lower token price. The unit that matters is the completed task, and almost nobody is measuring it.
On 21 September, Bloomberg reported that Harvey, the legal-AI company that had just raised $550 million at a $15.5 billion valuation, saw gross margins fall from roughly 50% at the start of 2026 to −50% by June. The trigger was a March update to its AI agents: customer usage spiked, and token consumption rose twentyfold over the year. Margins returned to positive territory after August, when Harvey shipped Tenet – its first in-house model, a Moonshot Kimi K3 base post-trained with Fireworks for long-horizon legal work.
Two caveats belong next to those numbers before anyone builds a strategy on them. The margin figures come from a single person familiar with the matter, and Harvey declined to comment on its financials. And Bloomberg's account attributes the recovery to the Tenet launch and other changes to how Harvey uses AI – so the swing is not a clean experiment isolating the model switch.
A −50% gross margin means paying your suppliers about $1.50 for every dollar of revenue. That is not a procurement problem. It is a structural one, and the structure is worth naming precisely, because the popular reading of it is wrong.
The mismatch is the shape, not the price
Harvey sells annual per-seat licences with unlimited usage, and pays its model providers per token.
Sit with that for a second. Revenue is fixed at signature. Cost is metered and uncapped. Between those two facts sits a product whose entire value proposition is that it will do more work on the customer's behalf over time. Every capability improvement – longer task horizons, more autonomous retries, deeper research loops – increases consumption against revenue that cannot move until renewal.
That is not a pricing mistake anyone was careless about. It is the default configuration of nearly every enterprise AI application sold in the last three years, because per-seat licensing is what enterprise buyers know how to purchase and what procurement knows how to approve. It worked fine when the product answered questions. It stops working the moment the product runs loops.
Call it the pricing-shape mismatch: fixed-shape revenue against variable-shape cost, with a product roadmap that systematically increases the variable side. The March agent update is the tell. Shipping a better agent was a margin event. In a business with this shape, your engineering roadmap and your cost of goods are the same document, and improving the product makes the unit economics worse.
Any operator selling an agentic product can check their own exposure in an afternoon. Take your revenue model and your COGS model, and ask whether they have the same shape. If revenue is per seat and cost is per token, you are carrying Harvey's risk, and the size of it is whatever multiple your usage grows by before your next renewal cycle.
The savings did not come from cheaper tokens
Here is where the consensus reading breaks down arithmetically.
At published rates, Fireworks serves Kimi K3 at about $3 per million input tokens and $15 per million output, against roughly $5 and $25 for Claude Opus 5. That is a meaningful discount – about 40%. It is nowhere near enough to explain the cost reductions Harvey describes, which run to roughly one-tenth the cost per cell on review tables and a 90% reduction in cost per query on firm knowledge.
Fireworks' own published figures show where the difference actually comes from. Tenet costs $5.92 per task on the Legal Agent Benchmark, against $5.62 for the base Kimi K3 model – slightly more per attempt. What changed is the all-pass rate, which rose from 10.8% to 19.7%. Divide cost by success rate and cost per fully passed task falls from roughly $52 to roughly $30.
Post-training did not buy a discount. It bought reliability, and reliability is what collapses cost in an agentic system, because the dominant cost driver is not the price of an attempt but the number of attempts a task requires. A cheaper model that fails more often is more expensive. A more expensive model that finishes is cheaper. Per-token pricing – the number every procurement conversation anchors on – measures the input and tells you almost nothing about the bill.
So the operative unit is cost per completed task. It is the only figure that reconciles token price, success rate, retry behaviour, and human rework into something you can put in a margin model. Harvey's own benchmark numbers imply the all-pass rate was still under 20% after post-training, which is worth stating plainly: even the fixed version fails most long-horizon legal tasks on first pass. That is the honest state of agentic reliability, and it is precisely why the completed-task denominator matters so much.
The landlords cut the rent the same week
The tempting conclusion – frontier models are a tax, open weights are the escape, the app layer has won – ran into the market almost immediately.
Within roughly a day of the Harvey reporting, Anthropic released Claude Opus 5.5 priced below Opus 5, and about ninety minutes later OpenAI released GPT-6 Sol at about half of GPT-5.6's promotional API pricing along with GPT-6 Luna at ten cents per million input tokens – below the Fireworks serverless rates for the very Kimi K3 base Harvey had moved to. Five days before the Harvey story, OpenAI had shipped Astra for Law, aimed squarely at Harvey's customers.
Read those together and the picture is not an inversion where the app layer escapes and the labs concede. It is a collision. Applications are moving down the stack into their own weights; labs are moving up the stack into applications; and both are cutting price to hold position. Anthropic, for its part, has publicly reminded investors that Harvey still needs Opus for its hardest work, and Harvey's stack remains hybrid by design.
Which reframes what in-housing actually bought. Some of it is cost. A great deal of it is leverage. A company that has demonstrably shipped a production model on open weights negotiates differently from one that has not, and the option to leave is worth something even on days you do not exercise it. Harvey is also encouraging its customers to post-train their own open-weight models – its funding announcement is framed around legal teams owning their intelligence – which is a strategic position, not a cost-reduction programme.
What operators should actually do
Check whether your revenue and your costs have the same shape. Per-seat unlimited against per-token metered is the configuration that took Harvey from +50 to −50 in six months. Either cap usage, move to consumption or outcome pricing, or hold enough margin headroom to absorb a twentyfold increase. Model your token consumption at ten to twenty times current levels and see whether the business survives it. If it doesn't, the problem is the contract shape, not the vendor.
Change the unit you measure and the unit you demand. Cost per token is a supplier's metric. Cost per completed task is yours. Instrument success rates per task type, and make every AI vendor you buy from report cost per completed task rather than per-seat pricing with a token footnote. This is also the right internal metric for build-versus-buy on models: the question is never "is this model cheaper," it is "does this model finish more often at comparable cost per attempt."
Treat capability upgrades as COGS events. In an agentic product, shipping a better agent increases consumption. Route every roadmap item that extends autonomy or task horizon through a unit-economics review before it ships, the same way you would route a headcount request. The March update is the cautionary example: a product win and a margin event, arriving together and reviewed separately.
Build the ability to switch before you need it, and value it as an option. A routing layer that can send each request to the cheapest model clearing the quality bar for that task is worth having even if you never leave your primary vendor – Decagon now routes about 80% of customer queries through its own models. The instrumentation that makes routing possible is the same instrumentation that makes cost per completed task measurable, so the two investments are one investment.
If you are buying, ask the concentration question. Which base models does this vendor depend on, what happens to their economics if pricing changes, and can they route around it? A vendor whose margin is hostage to a supplier's price list has a risk that eventually becomes your renewal problem.
Bottom line
The Harvey story is being told as cheap open weights beating expensive frontier models. The numbers say something less convenient and more useful: a company sold fixed-price contracts against metered costs, shipped a capability upgrade that multiplied consumption twentyfold, and rescued its margin primarily by making tasks succeed more often rather than by paying less per token. The frontier labs then cut prices below the open-weight alternative within a day, which tells you how much of the original thesis was about price and how much was about leverage.
The forward call: within two renewal cycles, per-seat unlimited pricing disappears from serious agentic products – replaced by usage tiers, task-based pricing, or fair-use caps – and cost per completed task starts appearing in vendor materials and procurement templates the way cost per seat does today. The tell will be the first enterprise AI vendor that publishes a success-rate-adjusted price, because that is a company confident its agents finish. Everyone still quoting per-token rates is quoting the input and hoping you don't ask about the output.
The model was never the product. The token was never the unit. The completed task is both.
Sources: Bloomberg, "Startups Like Harvey Embrace Open Models to Cut Reliance on Anthropic, OpenAI" (Rebecca Torrence and Natasha Mascarenhas, 21 September 2026) for the gross-margin arc (about 50% at the start of 2026 to −50% by June, sourced to a person familiar with the matter), the March 2026 agent update, the twentyfold rise in token usage, the attribution of recovery to the Tenet launch "and other changes to how it uses AI," and Harvey's declining to comment on specific financials; secondary coverage via The Next Web, "AI model costs are pushing startups towards cheaper open weights" (21 September 2026), which also names Abridge (building a clinical model on Nvidia's open weights), Decagon (routing 80% of customer queries through its own models), Rogo, and Ramp – which raised $750M in June and is weighing training for the first time, per co-CEO Karim Atiyeh. Harvey Tenet specifics – Kimi K3 base, post-trained with Fireworks for long-horizon legal work – per Harvey's research post of 20 August 2026; the $550M raise at a $15.5B valuation per Harvey's 9 September announcement and TechCrunch (Bloomberg cites $15.6B). Fireworks and Harvey cost figures – $3/$15 per million tokens for Kimi K3 against $5/$25 for Claude Opus 5; Tenet at $5.92 per Legal Agent Benchmark task versus $5.62 for base Kimi K3; all-pass rate rising from 10.8% to 19.7%; roughly one-tenth cost per cell on Review Tables and a 90% reduction in cost per query on Firm Knowledge; and Harvey's per-seat unlimited licensing against per-token supplier costs – per Fireworks' published write-up and Harvey's blog as analysed by beri.net. The subsequent price moves – Claude Opus 5.5 below Opus 5, GPT-6 Sol at roughly half GPT-5.6 promotional pricing, and GPT-6 Luna at ten cents per million input tokens, below Fireworks' Kimi K3 serverless rates – and OpenAI's Astra for Law shipping five days before the Harvey story, per contemporaneous coverage collated by Facts Are Friends and BuildFastWithAI's 22 September roundup. Anthropic's statement that Harvey still requires Opus for its hardest tasks per Object Edge. Cognition's selection of the same Kimi K3 base for SWE-2 on 10 September per BuildFastWithAI. Cross-references to prior Signal Memo coverage: the recognizable-outcome trap, the deflection illusion, substrate vs. broker. What is original to this memo: the "pricing-shape mismatch" framing, the arithmetic demonstration that token-price differences cannot account for the reported savings, the identification of cost per completed task as the operative unit, the reading of in-housing as option value rather than cost reduction, and the operator prescriptions.